
Administrative data analysis involves taking data that is collected as part of an agency’s operations and using it to increase our understanding of a program or policy. These insights can guide improvements or future decisions related to the program or policy in question. There are many ways to use administrative data, but we generally use it to (1) describe what’s happening, (2) visualize where things are happening, and (3) predict what might happen next.
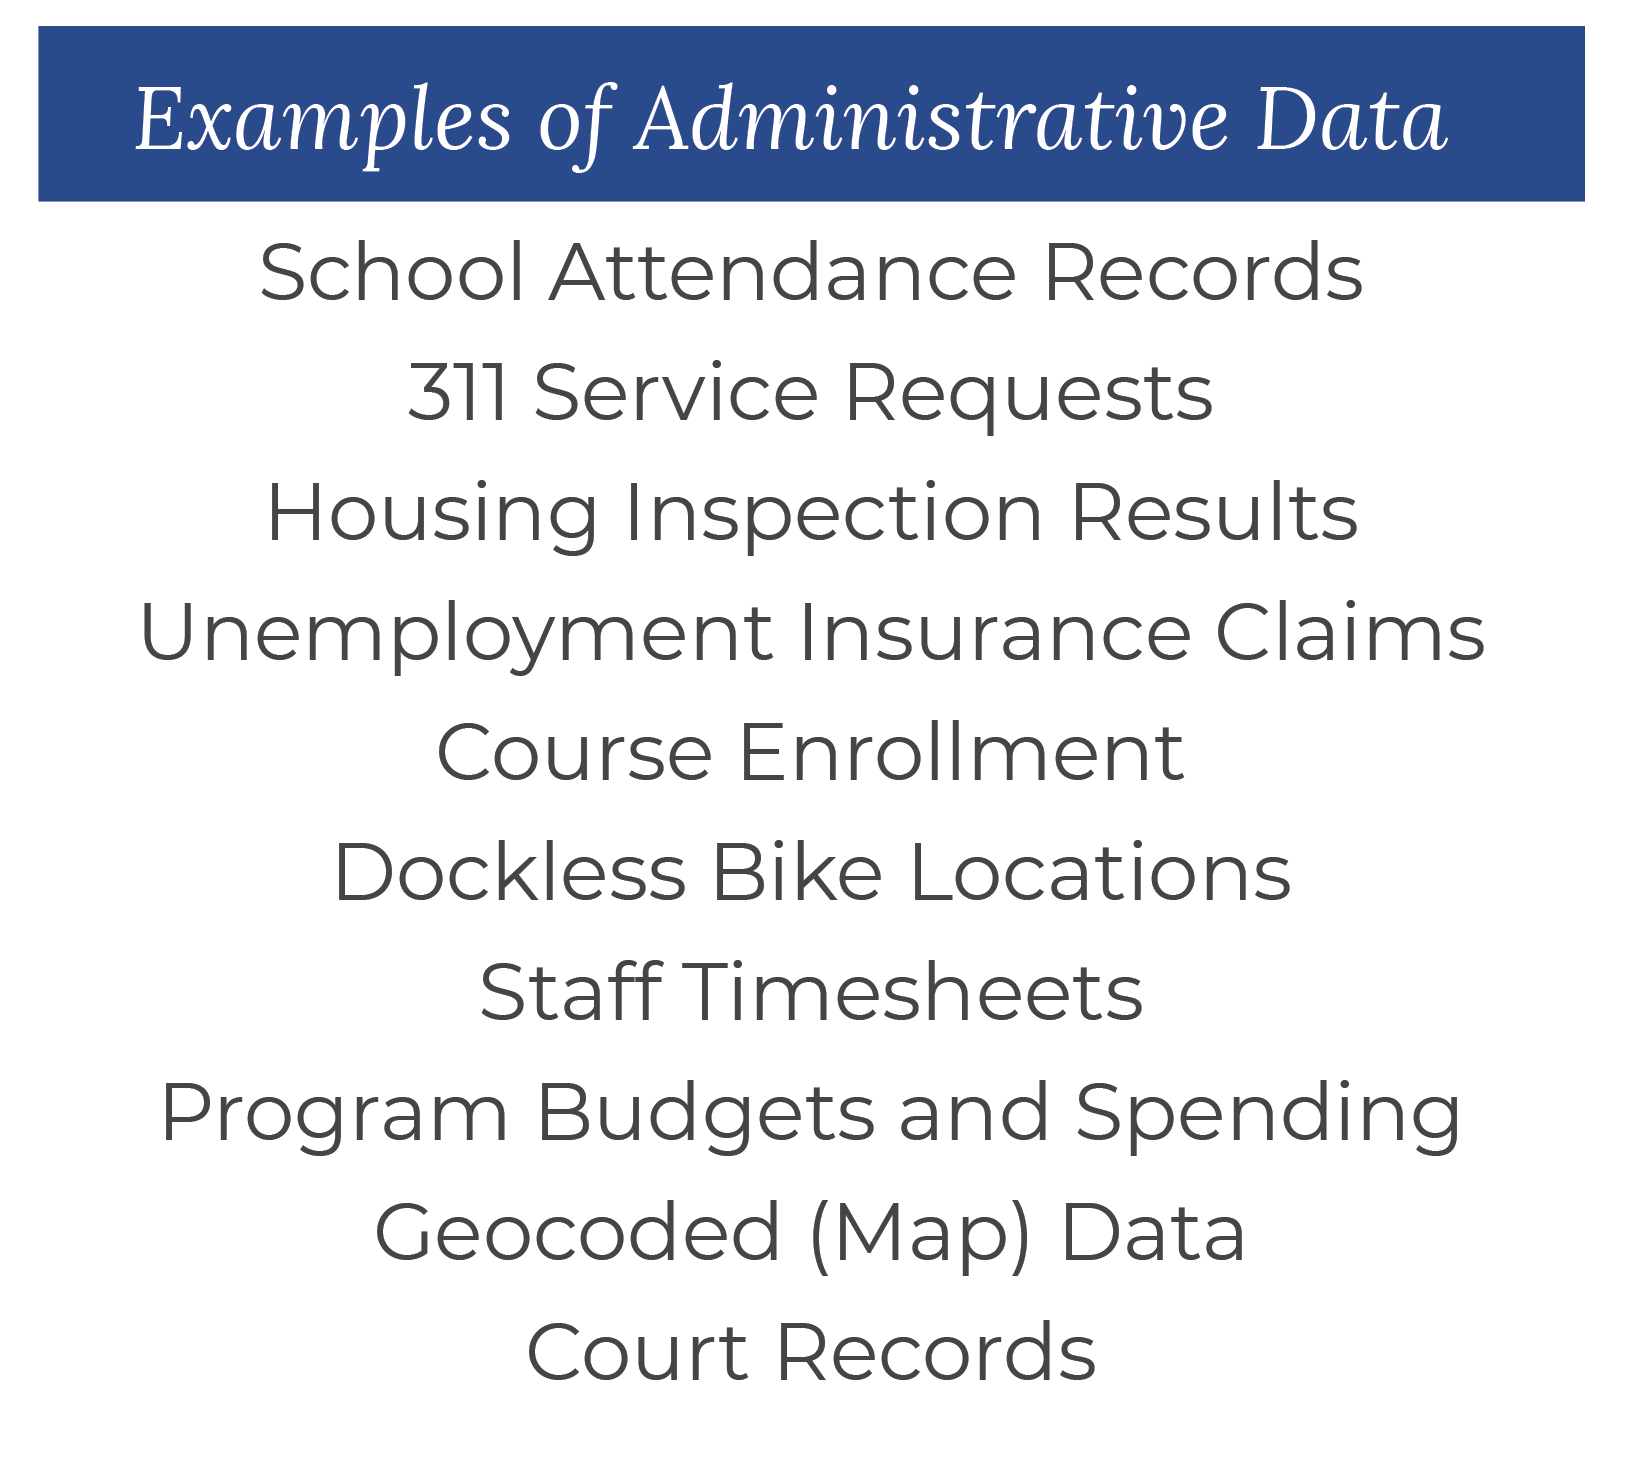
Most Lab analyses involve administrative data. When we analyze it in a straightforward way (without predictive modeling or causal evaluation), we call that doing “administrative data analysis.” If we wanted to use administrative data to say whether a program or policy works, it requires a more complex analysis, which would fall into the category of “evaluations.”
Let’s explore administrative data analysis approaches with a hypothetical example: a DC government agency is partnering with a community-based organization to run an after-school tutoring program.
What can we learn through descriptive analysis?
We often start with one type of administrative data analysis: descriptive analysis. Descriptive analysis uses basic statistics to answer questions about the program, like: How many students does the tutoring program serve? For how long do students typically participate in the program? Which grades do most students in the program come from? We use these counts, averages, and tabulations to determine which aspects of a program we should investigate further.
After we answer some of these basic questions, we might dig deeper into how the program operates. For example: How often do students meet with tutors? What subjects do students work on most often with their tutors? How many students are assigned to each tutor? Together, the answers to these questions help build a clear picture of program activity.

An illustration of how a Lab researcher might approach administrative data analysis for an after-school tutoring program.
What can we learn by visualizing the data?
It often helps to visualize the data using charts so that information can be digested quickly, and patterns or relationships can be revealed more easily. A simple line graph, for instance, can show just how much participation in the tutoring program has increased from year to year.
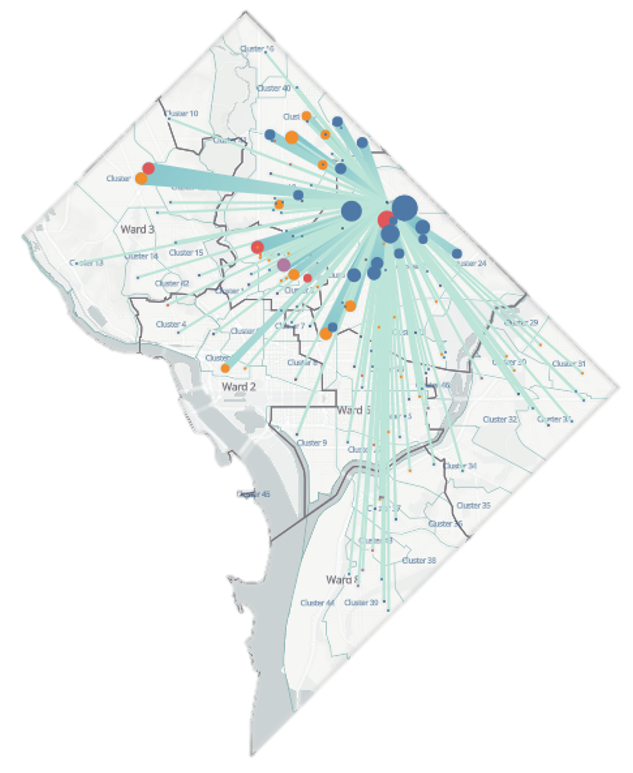
Sample map from The Lab’s work on how transportation barriers relate to student attendance.
When data have information related to location, like addresses or coordinates, we can visualize it using maps. This is the first step of geospatial analysis. Geospatial analysis helps us see things like clusters of common occurrences, distances between things, or relationships between neighborhood-level characteristics and important outcomes.
Suppose the tutoring program is struggling with student attendance. Mapping where students in the program live could provide helpful context if the agency thinks travel barriers might be an issue. Adding attendance data to the map (e.g., by making each dot a different shade based on a student’s attendance rate) could reveal whether students who live farther from their school tend to miss more sessions. Plus, having a map of where students live could reveal if there are clusters of students living near community resources like libraries or rec centers, which might be more convenient locations to host the tutoring sessions.
Descriptive and geospatial analyses can take us far. They clarify what a program is doing and who it serves. But administrative data can also support more forward looking inquiry.
Can we use administrative data to predict what will happen next?
In some cases, we might want to know whether trends we see in the data right now will extend into the future. We can use administrative data to make estimates about future values through a process called forecasting and can answer questions such as, *how many students do we anticipate being in the program next year? *Forecasting uses mathematical models that identify trends and patterns in pre-existing data and then create predictions about future data. (Note: forecasting differs from predictive modeling in that it generally only uses historical data on a single variable.)
For example, if we had previous program attendance data, we could run a forecasting model to predict daily attendance for next month. Say the model finds that attendance is always lowest on Fridays relative to the other days and therefore predicts next month will see relatively low attendance on Fridays again. The organization can then plan accordingly, perhaps by boosting student engagement efforts on Fridays or adjusting staffing on different days of the week.
Because forecasts only rely on past patterns, they are limited in how accurate their future predictions can be. To reflect this uncertainty, models provide a range of plausible values, known as a “prediction interval” or “confidence interval”, in addition to the single value they provide as their estimate. So, a forecasting model might estimate 100 students will attend next Monday’s session but also indicate that the true value could range from 90 to 110. The organization might then want to ensure that it has enough available tutors for 110 students on Monday.
What considerations do we keep in mind when using administrative data?
Using administrative data offers several advantages: the data already exist, they are created as part of a program’s normal operations, and they are available almost immediately. That said, some of these benefits are also risks.
1. Data quality. While it’s great that the data are already being collected for a program, this also means they may not be as clean as if they had been specifically gathered for research purposes. When frontline staff collect data for their own purposes, this often requires some judgement calls on our end during analysis. For example, if somebody is missing income data, does that mean they have no income or that their income was never recorded?
Solution: We work closely with our agency partners to understand the data and its gaps. And when we report our findings, we are transparent about these limitations and assumptions, and we frame our conclusions in a way that recognizes the data’s imperfections.
2. Privacy. Because the data already exist as part of a program’s operations and residents usually can’t “opt out” of their data being collected, we take great care to ensure we respect residents’ privacy. This is especially true when we’re combining data from multiple sources. For instance, residents may know that the workforce development centers have their employment records and that the Medicaid office has their health history, but residents might not want their job counselors to know about their health issues.
Solution: We remove names and identifiers from the data we’re analyzing, and we report information only about groups of people, not individuals. We also have strong safeguards in place to make sure the data is secure when it’s shared with us, when we’re analyzing it, and when we dispose of it.
3. Scope creep. Data from program operations often contain more variables than we necessarily need to answer our research questions. On the one hand, this can spark new questions and insights while we’re digging into the data. On the other hand, this can also lead us to fall down a rabbit hole of data and interesting questions, potentially losing sight of our original goals, which is known as “scope creep.”
Solution: We always start with a strong sense of the overall goals of the analysis. We commit ourselves to one specific research question and make sure all of our work is in service of answering that question.
How does The Lab use administrative data analysis
Now that you know how we use administrative data analysis, check out a few examples of how we’ve used these techniques to help Washingtonians:
- How do the District’s employment services support people experiencing homelessness?
- Can food benefits bridge the summer hunger gap?
- Are dockless bikes the right addition to the District's transportation options?
- Can a different forecasting model help better allocate resources for court-involved youth?
- How can we use data to make DC's criminal laws more fair?